Which Long Tail Keywords Should You Target First, and Why?
Which long tail keywords deserve targeting first? Clear criteria for judging intent, competition, and conversion potential before you write a word.
You have a spreadsheet with four hundred long tail keywords and the capacity to publish perhaps eight articles a month. The question is not whether these queries are worth chasing (they are: long-tail terms account for the bulk of search behaviour, and they convert better than head terms). The question is which twenty to thirty earn a page this quarter. That prioritisation decision is where most keyword strategies quietly fail, because teams sort by volume and call it done. This article answers the questions that actually decide the order: how to weigh intent against volume, what to do with zero-volume queries, how AI search changes the maths, and how to build a repeatable scoring method your whole team can defend.
Should you sort long tail keywords by search volume first?
No. Volume is a tiebreaker, not a ranking criterion. The first sort should be by intent fit: does the query describe a problem your product, service, or content genuinely solves, for a searcher who could plausibly become a customer or a loyal reader?
The reason is arithmetic. A long-tail query with 40 monthly searches and strong purchase intent will usually outperform a 400-search informational query that attracts the wrong audience. Research compiled by Yotpo in 2026 puts the conversion rate of long-tail terms at roughly 2.5 times that of head terms, precisely because specificity signals that the searcher has finished browsing and started deciding. If you sort by volume, you systematically bury your best commercial queries under vague informational ones.
There is a second, less obvious reason. Reported search volumes for long-tail queries are unreliable. Keyword tools estimate from samples, and at low volumes the estimates round to zero or cluster into wide bands. Treating "30/mo" as meaningfully different from "10/mo" is false precision. Treating "someone describing my exact use case" as different from "someone loosely curious" is real signal.
So the practical order is: filter for intent fit, then for winnability, then use volume to break ties among what survives.
How do you judge intent when the query looks ambiguous?
Read the query as a sentence a real person would say, then ask what outcome they want in the next ten minutes. Long-tail phrasing usually carries its intent in its modifiers, and the modifiers fall into recognisable groups.
Decision modifiers — "best", "vs", "alternatives", "pricing", "reviews", "for small business" — signal someone comparing options. These are commercial-investigation queries, and they belong near the top of your list if you sell anything in the category. Problem modifiers — "how to fix", "why is", "not working", "template", "checklist" — signal someone mid-task. They convert indirectly but build topical authority and earn links. Definition modifiers — "what is", "meaning", "examples" — signal early-stage researchers. Useful, but rarely urgent, and increasingly answered by AI Overviews without a click.
When the words alone do not settle it, look at the SERP. Type the query and note what Google returns: product pages and comparison posts mean commercial intent; how-to guides mean task intent; a featured definition box means the click-through opportunity is thin. The current page-one results are the best evidence of what Google believes the searcher wants, and fighting that belief is expensive.
One trap worth naming: some queries look commercial but are actually navigational. "Ahrefs long tail keyword tool" is someone trying to reach a specific page, not someone evaluating tools. Owning a competitor's navigational query rarely pays.
When does a zero-volume or tiny-volume query still deserve a page?
When three conditions line up: the intent is strong, the query represents a real recurring question, and the page can rank for a cluster of similar phrasings rather than one exact string.
The zero-volume problem is well documented. An aggregated index of 17,556 business AI-service keywords across the US, UK and Australia, published in September 2026, found that 61.2% of the keywords reported zero measured monthly volume — yet demand concentrated in a long tail of specific questions that tools simply fail to count. Ahrefs has made the same point for years in its long-tail keyword research: individually tiny queries collectively make up the majority of searches, and Google matches pages to far more phrasings than any tool tracks.
The tell is pattern repetition. If your sales calls, support tickets, community threads, or Google's autocomplete and People Also Ask boxes keep surfacing the same question in slightly different words, the demand exists even when the tool says zero. A query like "how to brief a freelance writer on schema markup" might show no volume, but its family ("writer brief for structured data", "content brief schema requirements") is a real, recurring need.
The caution: zero-volume bets should still clear the intent bar. A page for a precise, high-intent question nobody has measured is a good bet. A page for a vague question nobody has measured is a gamble on both counts.
How much should competition level change your ordering?
A lot, but only after intent. Competition decides when you can win, not whether the win matters.
For most sites, the workable rule is to sequence long-tail targets from lowest competition upward, using each published page to build the topical authority that makes the next tier winnable. A site with modest domain strength that opens with its most contested queries tends to publish into silence for six months and lose internal support for the whole programme. The same site that starts with uncontested, high-intent queries builds traffic, internal links, and crawl history that compound.
Competition metrics need the same scepticism as volume. Keyword difficulty scores are proxies built mostly from backlink counts of current rankers, and they miss two things that matter for long-tail terms: content quality on page one, and SERP feature crowding. A "LOW" difficulty query whose first page is entirely exact-match, well-maintained guides from Adobe and Shopify is not low difficulty in practice. A "MEDIUM" query answered only by forum threads and a 2019 blog post is wide open.
A quick manual check beats the score: open the top five results and ask honestly whether your page would be better than at least three of them. If yes, the query is winnable regardless of the number. If no, either improve the angle or defer it. This is the kind of judgement SiaSEO bakes into its calendar automation — keyword difficulty, SERP composition, and your site's existing topical coverage get weighed together before a query is scheduled for drafting, so the queue reflects winnability rather than raw volume.
Has AI search changed which long tail keywords to target first?
Yes, and in a specific direction: question-shaped, highly specific queries matter more, but some purely definitional ones matter less.
The mechanism is straightforward. AI Overviews and chat assistants answer questions directly, and they trigger most often on exactly the phrasing long-tail strategy targets. Reporting cited by Neal Schaffer in his 2026 analysis of longtail keywords found AI summaries appearing on 53% of searches with ten or more words and 60% of question-form searches beginning with "who", "what", "when", or "why". BrightEdge tracking, cited by Sydekar, puts eight-word-plus queries at seven times more likely to generate an AI Overview than shorter ones.
That cuts two ways. For pure definitions ("what is a canonical tag"), the AI answers on the results page and the click often never happens. Deprioritise those unless the definition supports a broader page. But for questions with nuance — comparisons, procedures, decisions, anything where the searcher wants depth — being the cited source inside the AI answer is the new position one. TripleDart's SaaS playbook argues that citation eligibility, not search volume, is now the right unit of analysis: a page lifted by Perplexity, ChatGPT, or Google's AI Overview contributes brand pull that a conventional ranking can no longer promise.
Practically, this means two adjustments to your ordering. First, favour queries where a complete, well-structured answer can be extracted and cited: clear question, direct answer in the first sentence, supporting detail. Second, check whether your target queries already trigger AI Overviews, and if so, study which sources get cited. Those citations reveal what format and depth the answer engines reward.
What scoring method actually works for prioritising a long list?
A simple weighted score across four factors beats both gut feel and single-metric sorting. Score each query from 1 to 5 on each factor, weight them, and rank.
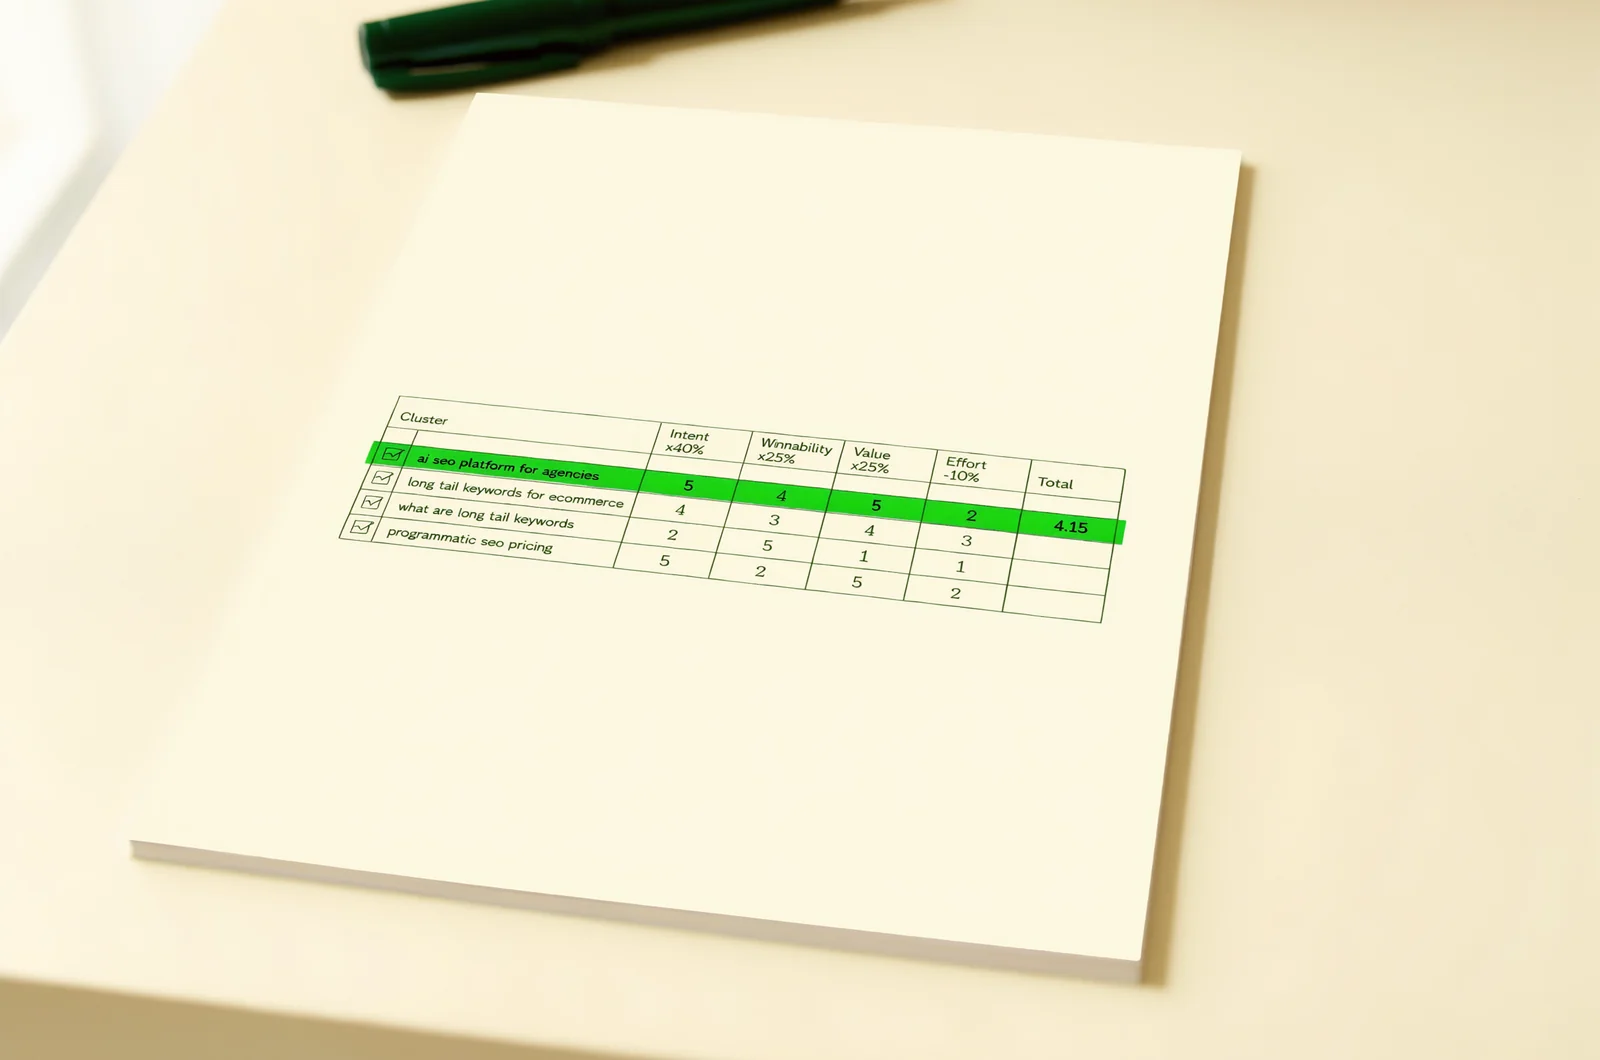
| Factor | What you are measuring | Suggested weight |
|---|---|---|
| Intent fit | How closely the query maps to a problem you solve for a plausible buyer | 40% |
| Winnability | Realistic chance of page one within 6 months, judged from actual SERP inspection | 25% |
| Business value | Revenue or pipeline influence if the page converts | 25% |
| Effort | Research depth, assets, and expertise the page needs | 10% (subtract) |
Intent fit dominates because a page that ranks for the wrong query produces traffic you cannot use. Winnability and business value share second place because either one at zero kills the business case on its own. Effort is a small penalty: it should break ties, not veto high-value targets.
Two refinements make the method sturdier. First, cluster before you score. Group near-duplicate phrasings ("best crm for freelance designers", "crm for solo graphic designers") and score the cluster once, since one page will serve all of it. This stops the list from double-counting the same opportunity and reveals that many "small" queries are one medium opportunity wearing different hats. Second, re-score quarterly. SERPs shift, AI features spread, and a query deferred in January can be wide open by April.
Teams running this at scale usually hit a throughput problem before a judgement problem: scoring four hundred queries by hand takes days. This is where an automated pipeline earns its keep — SiaSEO generates a prioritised 7-day content calendar from a site's URL by doing this kind of clustering and scoring continuously, so the quarterly re-score becomes a standing process rather than a project.
How many long tail keywords should one page target?
One cluster, not one string. A page should own a primary query and the family of close variants that share its intent, which is typically five to twenty phrasings.
The days of one page per exact-match keyword ended when Google got good at semantic matching, and the opposite extreme — one page absorbing dozens of loosely related queries — dilutes relevance and ranks for nothing. The test is substitution: if two queries would be satisfied by the same answer, they belong on the same page. If the answers would differ in any way the searcher cares about, they need separate pages.
Shopify's long-tail keyword guidance makes the ecommerce version of this point clearly: product and category pages should each map to a distinct intent, with supporting content catching the question-form queries around them. The same logic holds for B2B and SaaS. Your "best crm for freelance designers" page can also answer "what crm do freelance designers use", but it cannot honestly answer "how to invoice clients as a freelancer" — that is a different job, deserving its own page that links across.
When you brief the page, name the primary query and list the variants it covers. That keeps writers (human or AI) from drifting into adjacent intents that belong elsewhere in your architecture.
What should you do this week with your existing list?
Export your long-tail candidates, cluster them by intent, and score the top thirty clusters with the four-factor method above. Then check the SERP and AI Overview status of the top ten by hand before committing them to a calendar. That manual pass takes an afternoon and catches the mis-scored queries that any tool-generated list contains. If you want a lighter weekly habit, a simple spreadsheet scoring template — or an interactive prioritisation calculator that weights intent, difficulty, and value — turns the quarterly re-score into a thirty-minute review. Either way, the discipline that separates productive programmes from busy ones is the same: intent first, winnability second, volume last.