Best Keyword Research Tools in 2026, Tested and Ranked
Ten keyword research tools tested on the same seed terms and ranked on data accuracy, difficulty scoring, SERP features, and real monthly cost.
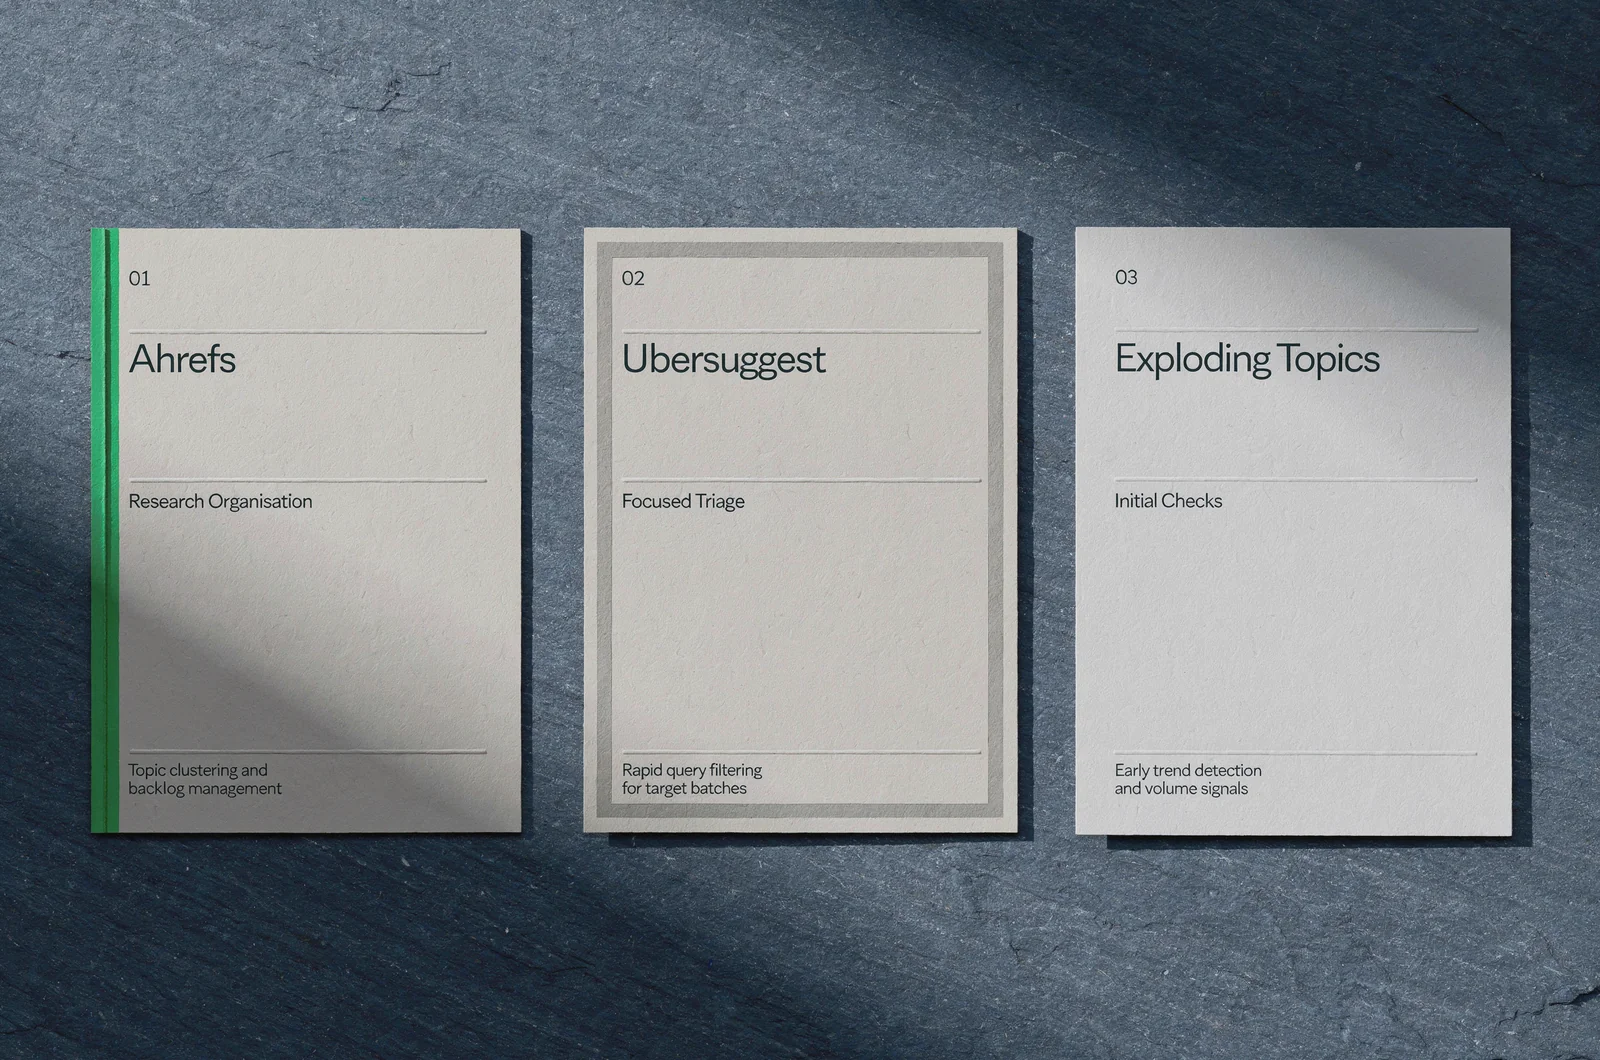
The best keyword research tools for a SaaS team or agency should help turn search demand into defensible publishing decisions. This shortlist ranks three options by documented workflow fit: Ahrefs for organising research, Ubersuggest for focused keyword triage, and Exploding Topics for initial keyword checks.
The testing claim needs a clear qualification. No completed hands-on, same-seed benchmark supports this shortlist, and independently verified accuracy results and current seat prices are unavailable. These are editorial rankings based on published product descriptions. The repeatable test below is a proposed purchasing evaluation, with no reported results.
That distinction matters when you are choosing software for several analysts or client accounts. A documented capability can justify a trial. An unverified performance claim should stay outside the purchasing score.
The ranking rewards usable keyword decisions
For this audience, the order prioritises documented support for turning seed terms into research that an editor or strategist can use. Organising related queries earns more weight than producing a large, undifferentiated list.
Four purchasing criteria should govern the eventual decision:
- Volume validation: whether estimates are usable for your target market, with clear settings and explanations for unexpected differences.
- Difficulty reliability: whether the score helps you choose realistic targets after inspecting the results and your own site.
- SERP coverage: whether the tool supplies enough context to judge intent, competing page types and the potential value of visibility.
- Cost per active analyst: what the required access and usage actually cost across the people doing the work.
The available descriptions support a provisional workflow ranking. They do not establish a winner for accuracy, SERP coverage or current pricing.
There are exactly three ranked entries because those providers have enough supplied product evidence to support a bounded recommendation. Adding names without comparable evidence would make the list longer without making the buying decision better.
Keep missing information marked as unknown. Request evidence for it before converting this shortlist into a purchase order.
Three research tools for a B2B shortlist
Ahrefs leads this editorial order for research organisation. Ubersuggest follows for focused triage, while Exploding Topics fits a narrower initial checking task.
1. Ahrefs for organising a research backlog
Ahrefs describes six keyword-idea report types, AI-assisted seed brainstorming, proprietary SEO metrics and search-volume data. It also describes clustering by Parent Topic or related terms on its Ahrefs.
The clustering support gives it the strongest documented fit for an agency or content team that needs to turn keyword discovery into candidate page targets. For that reader, the useful purchasing question is whether an analyst can move from a seed to a coherent group of queries without rebuilding the entire structure manually.
Make that the centre of your trial. Choose one product category, generate candidate terms and inspect the proposed groups. Ask an editor to decide which groups deserve separate pages, which belong together and which fall outside the business’s remit.
The limitation is evidence depth. Ahrefs’s description of reliable volume data remains a vendor claim here. There is no comparative error measurement, completed difficulty-validation test or verified seat-cost calculation supporting this ranking.
Parent Topic grouping also deserves editorial review before it becomes a publishing instruction. Require the reviewer to record the intended page, target audience and reason for combining the queries. That provides a checkable decision even when the grouping looks plausible.
Put Ahrefs first on your trial list if organising research is a recurring operational problem. Approve it only after testing how much useful structure survives the move from its output to your actual content brief.
2. Ubersuggest for focused keyword triage
Ubersuggest’s published description lists AI-generated keyword ideas, search volume, intent and difficulty scoring. It also mentions a lifetime payment option on Ubersuggest.
That combination supports a focused trial for a consultant or smaller content team. The task is to review a manageable set of opportunities, explain the choices and hand approved targets to a writer.
Its second-place position reflects that narrower decision workflow. The evidence supports inspecting several purchasing inputs together, but gives less detail about organising a larger research backlog than the Ahrefs description does.
During a trial, give the analyst a concrete deliverable: recommend five candidate pages, explain each page’s intent and identify the evidence behind its priority. Judge the resulting decisions before judging the number of suggestions returned.
The lifetime option needs separate commercial scrutiny. The information available here does not establish its current price, seat allowance, usage limits or the conditions attached to continued access. Any total-cost advantage remains unverified.
Request a written breakdown of what the proposed plan includes. Check who can use it, what happens when usage rises and whether the required work depends on additional charges.
Ubersuggest belongs second for readers whose immediate problem is disciplined keyword triage. Move it ahead of Ahrefs only if your trial produces comparable approved targets with a better documented total cost for the team that will use it.
3. Exploding Topics for initial keyword checks
Exploding Topics describes a free keyword checker with search-volume and difficulty information, backed by Semrush data, on its Exploding Topics. The cited description carries a 6 November 2024 publication date, so confirm its current scope before relying on it for a 2026 purchase.
Its clearest fit is a team that already has candidate terms and needs an initial check before committing more research time. That is a smaller job than managing the full research process across several clients or analysts.
Third place reflects the narrower documented scope. A checker can deserve a place in your process without becoming the main research subscription.
Test it against a list of terms you already understand. Record whether the available information helps you reject weak candidates, identify questions for further investigation or prepare a more focused paid-tool trial.
The evidence does not establish current access limits, export allowances, seat arrangements or a complete SERP-analysis workflow. It also provides no independent accuracy comparison with the other two entries.
Because its description identifies Semrush as the data provider, treat comparisons with another Semrush-powered view cautiously. Agreement between them should prompt questions about their underlying inputs before you count it as corroboration.
Use Exploding Topics for initial validation when that task matches your needs. Require evidence of the broader workflow before treating it as a replacement for a team research platform.
Put every shortlist through the same seed test
The final order should come from a controlled trial using your own market and publishing requirements. Give every tool the same seeds, country settings, evaluation period and requested deliverable.
For a hypothetical CRM team, the seeds could be CRM software, CRM implementation and CRM pricing. Those families let the reviewer examine category discovery, problem-led research and commercial intent.
A proposed scorecard could allocate 30% to volume validation, 30% to difficulty assessment, 20% to SERP coverage and 20% to total cost. Agree the weights before viewing results. Record missing evidence as unknown, and keep it separate from poor performance.
Volume validation against the queries you recognise
Record the selected country, period and keyword treatment alongside every estimate. Separate exact terms from any broader groups the interface may present.
Choose a subset of queries for which your team has relevant historical context. Compare the estimates with that context and investigate substantial discrepancies. Avoid treating impressions for your own site as a direct measurement of total market demand.
These checks assess consistency and usefulness. They do not establish an absolute accuracy rate without a suitable independent benchmark.
For UK and Irish campaigns, request separate market outputs where available. Preserve the country setting in the exported record so a reviewer can interpret the number correctly.
Difficulty assessment against the ranking task
Take a sample of recommended opportunities and inspect the search results for each. Record the dominant page type, intent and the specific work your site would need to produce a credible answer.
Ask the reviewer to explain whether the recommendation fits your site’s authority, subject expertise and available production resources. Keep the difficulty score beside that explanation.
Your acceptance test should be practical: can the analyst justify pursuing, delaying or rejecting the term?
Use the site’s guidance on prioritising long-tail keywords to support the prioritisation discussion. Require a page-level recommendation for every accepted group.
SERP coverage against the value of visibility
Inspect the actual results and record the elements relevant to the purchasing decision: organic listings, answer panels, videos, local results or other prominent formats.
Then check what each tool captures. Note any missing context that the analyst must collect separately, along with the time that review takes.
The deliverable should explain the page you would publish, the result it could compete for and why that visibility matters to the business.
Keep country, device and review date beside the observation. Repeat disputed checks under the same conditions before awarding the SERP-coverage score.
Count seats, limits and review time together
The cost winner should be the tool that supports the required work at an acceptable total cost. Build the calculation around active analysts and the tasks they must complete.
Start with a simple formula:
Effective monthly cost per active analyst = (subscription + seat add-ons + expected usage charges) ÷ active analysts.
Record billing currency, tax treatment and monthly versus annual commitments consistently. Request written confirmation of any term that could change the calculation.
Access limits deserve their own line in the buying worksheet. Check the allowances relevant to your trial, including research requests, exports and any functions the team expects to use regularly. Confirm the consequences of exceeding them.
Review effort belongs beside the subscription calculation. During the trial, record analyst time spent cleaning the output, checking recommendations and assembling approved briefs. Compare tools against the same deliverable.
A useful interactive calculator would accept subscription costs, additional seats, expected usage charges and monthly review hours. It would show cost per active analyst and cost per approved brief, with assumptions visible beside the result.
Do not award a cost score from an advertised starting price alone. Obtain the plan details for the number of people and volume of work you actually expect.
Keep AI research connected to editorial approval
AI-assisted research changes the purchasing decision when it affects the work between keyword discovery and an approved publishing brief. Evaluate that handoff during the trial.
Byword’s AI keyword research description lists intent classification, topic clustering, SERP analysis and a content-production workflow. Those are vendor-described capabilities; they do not establish comparative accuracy or operational savings.
For your own evaluation, choose one proposed topic and follow it through the entire approval process. Require the record to preserve the target market, reader need, intended page, business relevance and supporting evidence.
Ask an editor to review the recommendation before drafting starts. Measure the corrections needed to make it publishable. A useful trial result includes both accepted recommendations and rejected ones, with reasons.
If SiaSEO is part of your content-operations shortlist, assess it separately from the three research tools ranked above. Ask the same questions about research evidence, editorial approval and control over the final publishing decision.
Keep automation savings conditional until you have measured them. Compare time spent reviewing completed briefs, correcting factual problems and resolving competing page targets. Use the same quality threshold across every workflow.
For an agency, include the client’s approval requirements in that threshold. For an internal SaaS team, include ownership of product facts and audience positioning.
Approve the workflow when its records let another reviewer reconstruct why a topic was selected and who authorised the resulting page.
Questions that change the purchasing decision
A purchasing shortlist becomes more useful when it resolves the questions that could change the trial order or the subscription decision.
Which tool should an agency trial first?
Start with Ahrefs if organising a recurring research backlog is the main problem. Give it a client-specific deliverable and assess the structure of the resulting recommendations.
Trial Ubersuggest first when the workload is a focused set of keyword decisions and commercial terms could determine the purchase. Use Exploding Topics for initial checks when a full research subscription is still under consideration.
Can search volume decide which page to publish?
Use volume as one input in the decision. Require a clear reader need, a relevant business outcome and a credible publishing plan before approving the page.
If two candidates have similar estimated demand, ask the reviewer to explain which one better fits the site’s offer and available expertise. Record that reasoning alongside the estimate.
Does an AI suggestion establish a realistic ranking opportunity?
Require supporting evidence before accepting it. Ask what the recommendation depends on, how the current results were assessed and which site-specific constraints were considered.
Keep generated suggestions outside the approved calendar until a reviewer can defend the intended page. Treat any likelihood-of-ranking statement as unverified unless its measurement and validation are available.
Can UK and Irish campaigns share one evaluation?
Use the same evaluation procedure, with separate market settings and recorded outputs. Check whether the proposed topics, terminology and competing pages fit each campaign.
If a tool cannot provide the required market view, record that limitation before purchase. Agree how the missing information will be collected and include that work in the cost calculation.