Reading AI Benchmark Rankings Before You Pick a Content Model
Learn to read AI benchmark rankings: what each leaderboard measures, where scores mislead, and how to shortlist a model for SEO content.
Use an AI benchmark ranking to choose candidates for a content trial. Before approving a model, check what the leaderboard measures, whether its score differences support a decision, and how the candidates handle your actual briefs. For a marketing lead, the useful outcome is a documented shortlist tied to writing quality, factual accuracy and editorial effort.
Gather representative briefs, approved source material, brand guidance and an acceptance rubric before comparing models. Keep publication behind human review during the evaluation. Finish with an approved model for a defined task, a record of its limitations and a repeatable test for future replacements.
Set the content decision before opening a leaderboard
Define the content assignment that the model must complete. “Write better articles” leaves too much room for competing interpretations.
Specify the input, expected output and editorial constraints. For example, a proposed assignment might require a source-grounded B2B article in Canadian English, with a prescribed structure and claims restricted to an approved research packet.
Separate the stages you intend to evaluate:
- Research synthesis from supplied documents.
- Outline creation against a defined search intent.
- Article drafting within brand and structural rules.
- Revision after factual or editorial feedback.
Choose one stage for the first comparison. This gives reviewers a specific output to judge.
In a SiaSEO AI blog generation workflow, evaluate the drafting stage with its upstream brief and research attached. Include the context the model would receive during production.
Write the acceptance conditions before viewing model identities. Require traceable factual claims, compliance with the brief and an editorial effort limit your team can sustain. Record unresolved claims separately from stylistic preferences.
The starting document should fit on one page: task, inputs, constraints, acceptance conditions and reviewer responsibilities.
1. Match each benchmark to a content task
Select benchmark evidence according to the assignment you just defined. Ask what output was graded and which part of your workflow deserves a follow-up test.
Use this screening map to organise the evidence:
| Evaluation type | Content task to test next | Documentation to inspect |
|---|---|---|
| Rubric-scored writing | Drafting and revision against an editorial brief | Rubric, judge instructions and sample outputs |
| Reasoning tests | Reconciling constraints and drawing supported conclusions | Question format, scoring rules and permitted tools |
| Factual-answer tests | Answering questions within a defined knowledge scope | Reference answers, evaluation date and abstention rules |
| Human preference votes | Reader preference between competing responses | Voter selection, prompt mix and comparison procedure |
For writing evaluations, inspect the rubric before using the score. Check whether it rewards source support, audience fit and instruction compliance. Add any missing criteria to your own trial.
For reasoning evaluations, identify a corresponding content task. A useful trial might ask the model to reconcile conflicting product documents while preserving explicit uncertainty.
Set coding, mathematics or image-generation scores aside unless the assignment requires those capabilities. Record the connection whenever you retain one.
Use your article templates for intent to define the outputs under review. Compare a how-to draft against procedural requirements and a comparison draft against explicit comparison criteria.
Finish with a short evidence map that assigns each relevant benchmark to one production task.
2. Inspect how the ranking was produced
Create a record for each leaderboard entry before accepting its position as useful evidence. Capture enough detail to distinguish the model from the conditions under which it was evaluated.
Separate preference votes from scored answers
For vote-based rankings, inspect who voted, which prompts appeared and how responses were paired. Check whether the published method addresses answer order, response length and model identity.
Read the score according to its stated meaning. Keep preference ratings separate from percentages of correct answers.
For test-based rankings, inspect the scoring procedure. Determine whether grading uses exact answers, human judgement, another model or a combination. Record how partial credit and invalid responses are handled.
If the leaderboard uses an automated judge, inspect the judge instructions where available. Mark undisclosed details as unknown.
Capture the exact configuration
Record the model identifier, evaluation date and access method. Include the prompt, available tools, source access, output limit and number of attempts whenever disclosed.
Check whether the evaluated configuration matches the one you can use. A result produced with retrieval or multiple attempts needs that context beside the score.
Avoid transferring a score between similarly named versions without supporting documentation. Keep separate rows when the model identifier or evaluation conditions differ.
The expected result is a reproducible record. Another reviewer should be able to locate the same entry and understand its conditions. Leave any field you cannot verify blank or label it unknown.
3. Treat small score gaps as unresolved decisions
Inspect uncertainty before treating a higher score as grounds to select a model.
Imagine a hypothetical leaderboard with two entries scoring 84 and 82 on the same evaluation. Before favouring the first, inspect the sample size, uncertainty estimates and published comparison method. Follow the evaluator’s explanation of what the difference supports.
Where those details are absent, retain both candidates for the content trial. Record the gap without assigning it a stronger interpretation.
Avoid comparing numerical gaps across unrelated scoring systems. Keep each score beside its benchmark, scale and protocol.
Then define the minimum useful improvement for your operation. Require an observable difference, such as fewer unsupported claims, less revision time or more drafts meeting the acceptance rubric. Set the criterion before revealing model identities.
For example, you might require a candidate to pass every factual acceptance check while staying within a predetermined editorial time budget. Choose that budget from your staffing and publication requirements.
Produce a shortlist with a written reason for each inclusion. “Higher position” is incomplete; specify the task evidence, comparison limits and unresolved questions.
4. Examine test exposure and factual accuracy separately
Audit the evidence behind a content model’s score before relying on it for factual work. Keep questions about benchmark exposure separate from checks on the article’s claims.
Record uncertainty about evaluation exposure
Inspect any disclosure about whether test questions, reference answers or close variants were available during training or tuning. Look for information about evaluation holdouts and test construction.
Distinguish documented overlap from an unanswered question. Use “unknown” when the evidence does not establish exposure.
Keep the uncertainty attached to the affected benchmark. Avoid extending it into an unsupported claim about every result from that model.
Test support for individual claims
Build a source-grounded task using an approved document packet. Ask the model to draft from those documents and identify the support for material claims.
Include a question the packet cannot answer. Check whether the output marks the gap, omits the claim or supplies an unsupported answer. Define acceptable behaviour in the rubric beforehand.
Add a document conflict where your work requires reconciliation. Require the draft to preserve the conflict until an authorised source resolves it.
When evaluating retrieval and grounding approaches, record what evidence reached the drafting stage. Keep retrieval quality and the model’s treatment of retrieved material as separate evaluation fields.
Finish with a claim log. For each disputed statement, record the supporting passage, reviewer judgement and correction required.
5. Run a blinded trial on representative briefs
Test the shortlisted models against your publishing requirements. Keep the comparison controlled enough that reviewers can explain why a draft passed or failed.
Fix the inputs and review conditions
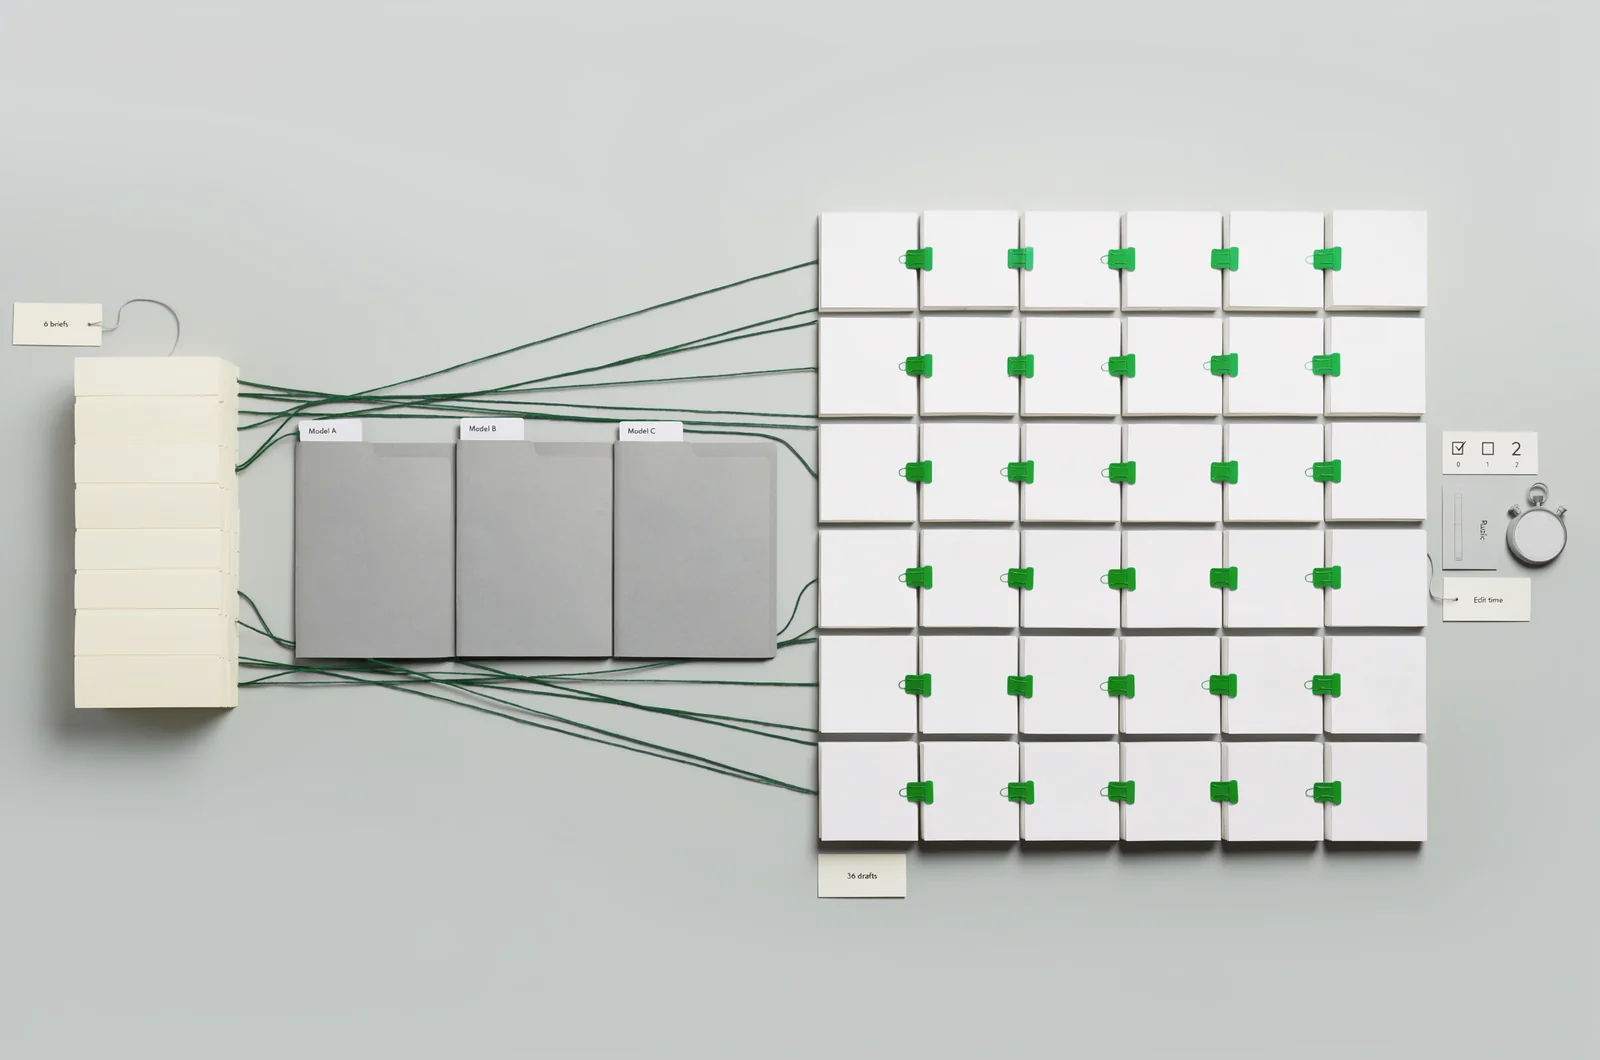
For an illustrative pilot, select six briefs and compare three candidates. Generate two drafts per brief from each candidate, for 36 drafts. Treat this as a proposed working design; choose a different size if your review capacity requires it.
Include routine assignments and difficult cases. Consider a brief with conflicting documents, one with sparse evidence and one with strict formatting requirements.
If Victoria-specific content is part of your workload, include an approved local brief. Require supplied evidence for geographic claims and Canadian spelling throughout.
Freeze the briefs, source packets and editorial rules during the first comparison. Use the intended production configuration for each model and document any differences in tools or generation settings.
Assign anonymous identifiers to outputs. Shuffle their order before review. Keep model labels and leaderboard positions outside the reviewer’s scoring sheet.
If a candidate cannot complete a brief under your production constraints, record the failure. Preserve the original input rather than silently simplifying the assignment.
Grade acceptance before editorial preference
Separate mandatory acceptance checks from graded criteria. An invented citation or unsupported material claim should trigger the factual failure rule you established before testing.
For the remaining criteria, a proposed three-point rubric can use:
- Zero when the draft fails the requirement and needs substantial rework.
- One when the draft meets part of the requirement and needs a defined repair.
- Two when the draft meets your publication standard.
Apply the rubric separately to structure, audience fit, brand voice and completeness. Write a concrete example beside each score definition.
Track editing time through to acceptance. Include verification, rewriting and any additional model runs needed to repair the draft.
Where reviewers disagree, record the disputed passage and rubric interpretation. Resolve that disagreement before using the scores to eliminate a candidate.
Retain the original outputs, revised drafts, scores and review notes. Confirm that every reported result can be traced to those records.
6. Turn the trial into a documented model shortlist
Choose candidates according to approved tasks and acceptance results. Keep the decision narrow enough to verify during production.
Apply acceptance checks before calculating averages
Remove a candidate from a task when it fails a mandatory acceptance condition. Investigate the failure before approving further use for that task.
Compare the remaining candidates on editorial effort and the criteria that matter to the assignment. Keep the individual scores visible beside any weighted total.
Choose weights before calculating the result. Document why source support, structural compliance or voice carries a particular weight. Preserve failures separately so an average cannot conceal them.
Calculate cost per accepted article using model charges and editorial labour across the trial. Include rejected drafts and repair attempts in the total cost, then divide by accepted articles.
Record the currency and labour assumption. Use CAD consistently if that is your budgeting currency.
Write the approval record and retest trigger
For SiaSEO’s multi-model routing, apply the evaluation to the specific stage under consideration. Approve research synthesis, drafting or revision according to its own results.
Document the chosen model version, approved task, required inputs, acceptance conditions and unresolved limitations. Name the person responsible for reviewing exceptions.
Run the selected candidate on a withheld brief before expanding its role. If it fails an acceptance condition, investigate the failure and repeat the affected test.
An internal model selector could accept task type, factual requirements, review budget and pilot results, then display eligible candidates with unresolved checks.
Set retest triggers for model-version changes, revised source inputs or changed editorial requirements. Keep the approval record beside the evaluation files.
Resolve doubts before approving a content model
Use the remaining questions to check whether the shortlist supports the publishing decision you need to make.
Should the highest-ranked model write every article?
Approve it only for tasks supported by your evaluation. Test a broader role before assigning it across the content operation.
A task-specific approval record should identify the model, its required inputs and the checks each output must pass.
What if the strongest writer fails factual review?
Keep factual acceptance as a mandatory condition. Investigate whether the failure arose from missing evidence, retrieval, instructions or treatment of the supplied material.
Repair the relevant stage and rerun the affected tests before approving publication.
What if two candidates remain tied?
Use a rule you selected in advance, such as lower cost per accepted article or less editorial time.
If neither candidate establishes a useful advantage, retain both as eligible options. Document the conditions under which you will revisit the decision.